Troubleshooting Systemd Service Failures: A Practical Linux Guide
When a Linux service fails, restarting it may restore operation briefly, but it rarely explains the cause. A reliable diagnosis follows the evidence: inspect the service state, read the journal, validate the unit file, test dependencies, apply a targeted fix, and verify the result after startup and reboot.
Understand What a Failed Systemd Service Means
A failed systemd service is a service unit whose most recent startup or execution ended unsuccessfully. The failed state records a symptom and an exit status, but the underlying cause may be a bad configuration, missing file, permission problem, unavailable dependency, or application error.
Systemd tracks several important states:
- active (running): the service started and is currently running.
- inactive (dead): the service is stopped without necessarily having failed.
- activating: systemd is still starting the unit or waiting for a prerequisite.
- deactivating: systemd is stopping the service.
- failed: the last activation attempt ended unsuccessfully.
- auto-restart: the service has stopped and systemd is preparing another attempt according to its restart policy.
A service can enter failed because its process returned a nonzero exit status, was terminated by a signal, or could not be launched at all. For example, an invalid ExecStart path may prevent the process from starting, while a process that starts and then exits may report a more specific application error.
Begin with the exact unit name, such as nginx.service, sshd.service, or myapp.service. Avoid guessing from a desktop notification. The unit name and failure timestamp determine which logs and configuration you need to inspect.
Check Service Status and Recent Logs
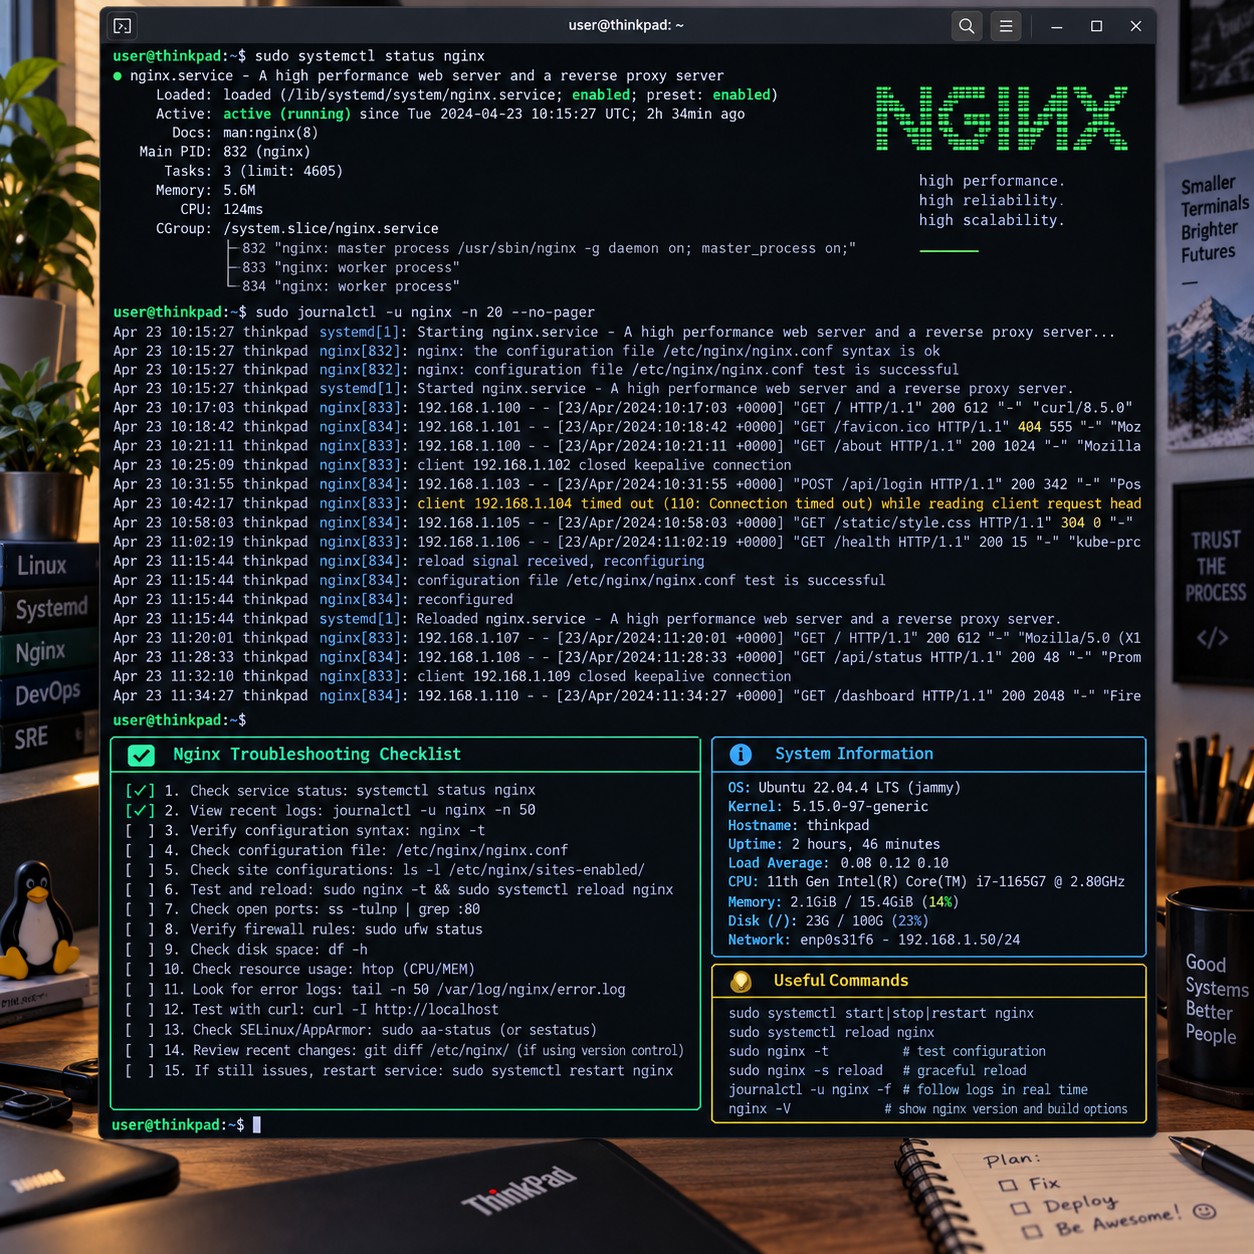
Use systemctl status for a concise failure summary and journalctl for the detailed event history. Together, these commands reveal when the service failed, which process exited, and what systemd or the application reported.
sudo systemctl status example.service
sudo journalctl -u example.service -n 100 --no-pager
The status output commonly includes the loaded unit-file path, enabled state, active state, main process ID, exit status, and recent journal lines. Read the final lines carefully. Messages such as No such file or directory, Permission denied, Address already in use, or Start request repeated too quickly point toward different investigations.
To view events from the current boot, use:
sudo journalctl -u example.service -b --no-pagerFor the previous boot, replace -b with -b -1, provided persistent journal storage is available. A precise time window can reduce noise:
sudo journalctl -u example.service --since "30 minutes ago" --no-pagerCheck the exit status rather than treating every failure as identical. Exit code 1 may represent an application configuration error, while exit code 127 often indicates a missing command or executable. Signals, such as a process being killed by the operating system, require a different line of inquiry. The application’s own logs may contain the decisive message, so inspect them when the journal only shows a generic exit code.
Authoritative command behavior and unit concepts are documented in the systemctl manual and related systemd documentation.
Inspect the Unit File and Service Configuration
Inspect the unit file and its effective configuration before changing anything. Confirm that ExecStart, environment variables, paths, user settings, and syntax match the software installed on the machine.
Find the unit file and show the configuration systemd is using:
systemctl cat example.service
systemctl show example.service
systemctl show example.service -p FragmentPath -p ExecStart -p User -p WorkingDirectory
Unit files may be supplied by the distribution, installed by a package, or placed by an administrator. Common locations include /usr/lib/systemd/system/, /lib/systemd/system/, and /etc/systemd/system/; exact paths vary by distribution. Files in /etc/systemd/system/ generally take precedence, so an override there may explain behavior that differs from the vendor default.
Review these directives in particular:
ExecStart: verify the executable exists and that arguments use the expected syntax.EnvironmentandEnvironmentFile: confirm variables and referenced files are present.WorkingDirectory: ensure the directory exists and is accessible to the configured user.UserandGroup: check that the account exists and can read, write, or execute required resources.Type: confirm that systemd’s expectations match how the application signals startup completion.
Validate syntax without starting the service:
sudo systemd-analyze verify /etc/systemd/system/example.serviceAfter editing a unit file or drop-in override, reload systemd’s manager configuration:
sudo systemctl daemon-reloadThis reload does not restart every service. It tells systemd to reread unit files. Editing a package-owned unit directly is also fragile because an upgrade can overwrite the change. Prefer a drop-in when appropriate:
sudo systemctl edit example.serviceDiagnose Dependencies, Permissions, and Startup Order
Dependencies and ordering determine whether a service receives the resources it needs at startup. Inspect both relationships and access rights instead of assuming that an active dependency guarantees a usable environment.
Display dependencies with:
systemctl list-dependencies example.service
systemctl list-dependencies --reverse example.service
Use the first command to see units required by the service and the second to see what depends on it. A failed mount, unavailable device, missing socket, or inactive prerequisite can block activation. The distinction matters: Requires= expresses a dependency, while After= expresses ordering. Neither directive alone solves every readiness problem.
Inspect the unit’s dependency and ordering properties:
systemctl show example.service -p Requires -p Wants -p After -p BeforeFor boot analysis, systemd can show a critical chain:
systemd-analyze critical-chain example.servicePermission failures often occur after systemd successfully launches the process. Test the configured account and inspect each parent directory:
namei -l /srv/example/config.yml
sudo -u exampleuser test -r /srv/example/config.yml
Check that a referenced socket, directory, certificate, or configuration file exists. If the service needs networking, remember that network-online.target indicates a synchronization point, not proof that a remote database or API is accepting connections. Applications may need their own retry logic or a correctly configured readiness check.
Security controls can also deny access. Review relevant journal messages before weakening protections:
sudo journalctl -b | grep -Ei "denied|apparmor|selinux"Correct ownership, paths, dependency declarations, or ordering first. Disabling SELinux, AppArmor, sandboxing, or other controls should not be the default troubleshooting method.
Test the Service Safely and Apply Fixes
Apply one targeted change at a time, then test with systemd and, when possible, in the foreground. This preserves a clear cause-and-effect trail and reduces the risk of masking the original failure.
- Save the original unit, configuration, and relevant error messages.
- Validate the application’s configuration with its supported command, if available.
- Check executable paths, files, permissions, ports, and required mounts.
- Reload systemd after unit changes.
- Start the service and immediately inspect its status and journal.
sudo systemd-analyze verify /etc/systemd/system/example.service
sudo systemctl daemon-reload
sudo systemctl start example.service
sudo systemctl status example.service --no-pager
sudo journalctl -u example.service -n 50 --no-pager
Foreground testing is useful when the application supports it. Running the exact command as the service account can expose missing environment variables, inaccessible files, or an invalid working directory. Do this carefully and avoid launching a second copy if systemd already has the service running. Stop the unit first when that is safe:
sudo systemctl stop example.service
sudo -u exampleuser /usr/local/bin/example --config /etc/example/config.yml
Do not rely on systemctl restart as a complete solution. Restarting clears the immediate process state, but it does not correct a malformed unit, missing dependency, wrong ownership, or broken application configuration. A controlled restart is appropriate after the cause has been addressed.
Handle Repeated Restarts and Boot-Time Failures
A service that repeatedly restarts usually has a process-level failure combined with an aggressive restart policy, or it is being launched before its required resources are ready. Inspect restart settings, rate limits, resource errors, and boot-target relationships together.
systemctl show example.service -p Restart -p RestartSec -p StartLimitBurst -p StartLimitIntervalUSec
sudo journalctl -u example.service -b --no-pager
Systemd may eventually report Start request repeated too quickly. Clearing the failed marker with systemctl reset-failed can permit another test, but it does not fix the loop:
sudo systemctl reset-failed example.serviceLook for a deterministic application error on every attempt. Also check memory pressure, disk space, file-descriptor limits, and port conflicts:
free -h
df -h
sudo ss -ltnp
sudo journalctl -k -b | grep -Ei "oom|killed process|out of memory"
For boot failures, identify whether the service is enabled and which boot target pulls it in:
systemctl is-enabled example.service
systemctl list-dependencies multi-user.target | grep example
After a repair, test a real reboot during an appropriate maintenance window. A service that starts manually but fails at boot may depend on a shell environment, mounted filesystem, secret, network endpoint, or directory that is absent during early startup.
Verify the Repair and Prevent Future Failures
Verify a repair by checking active state, clean journal output, expected application behavior, and successful boot behavior. A green status line alone is insufficient if the service is running but not serving its intended function.
Use a short verification sequence:
systemctl is-active example.service
systemctl status example.service --no-pager
sudo journalctl -u example.service --since "5 minutes ago" --no-pager
systemctl is-enabled example.service
Then test the service’s actual interface. Depending on the application, that may mean connecting to a local socket, checking a listening port, requesting a health endpoint, or running a client command. Confirm that the process runs under the intended user and that logs contain no new permission, dependency, or configuration errors.
For long-term reliability, document:
- the original exit status and journal message;
- the unit file or drop-in that changed;
- the dependency, ownership, or configuration correction;
- the commands used to validate the fix;
- whether the service was tested after reboot.
Enable automatic startup only after the service is correctly configured:
sudo systemctl enable example.serviceUse enable --now when you intentionally want to enable and start it in one operation. Keep monitoring the journal after deployment, especially when changing restart behavior or boot ordering. The most dependable workflow is evidence-led: preserve the error, change the smallest relevant setting, and verify both systemd’s state and the application’s real function.
Frequently Asked Questions
What does “failed” mean in systemd?
It means the service’s most recent activation or execution ended unsuccessfully. The state is a symptom; the exit status and journal usually reveal the specific cause.
How do I view the full logs for a failed service?
Run sudo journalctl -u service-name.service --no-pager. Add -b for the current boot, -b -1 for the previous boot, or --since to limit the time range.
Why does a systemd service keep restarting?
Common causes include an application that exits immediately, an invalid configuration, a missing file, a port conflict, resource exhaustion, or a configured Restart= policy. Inspect the journal before changing restart settings.
How do I reload systemd after editing a unit file?
Run sudo systemctl daemon-reload. Then start or restart the affected service deliberately and inspect its status and logs.
How can I make a service start automatically at boot?
Use sudo systemctl enable service-name.service. Confirm the result with systemctl is-enabled service-name.service, then test the service after a controlled reboot.